JFinBench
A continuously refreshable Japanese financial benchmark built from the latest editions of six professional certification exams.
Leaderboard
About JFinBench
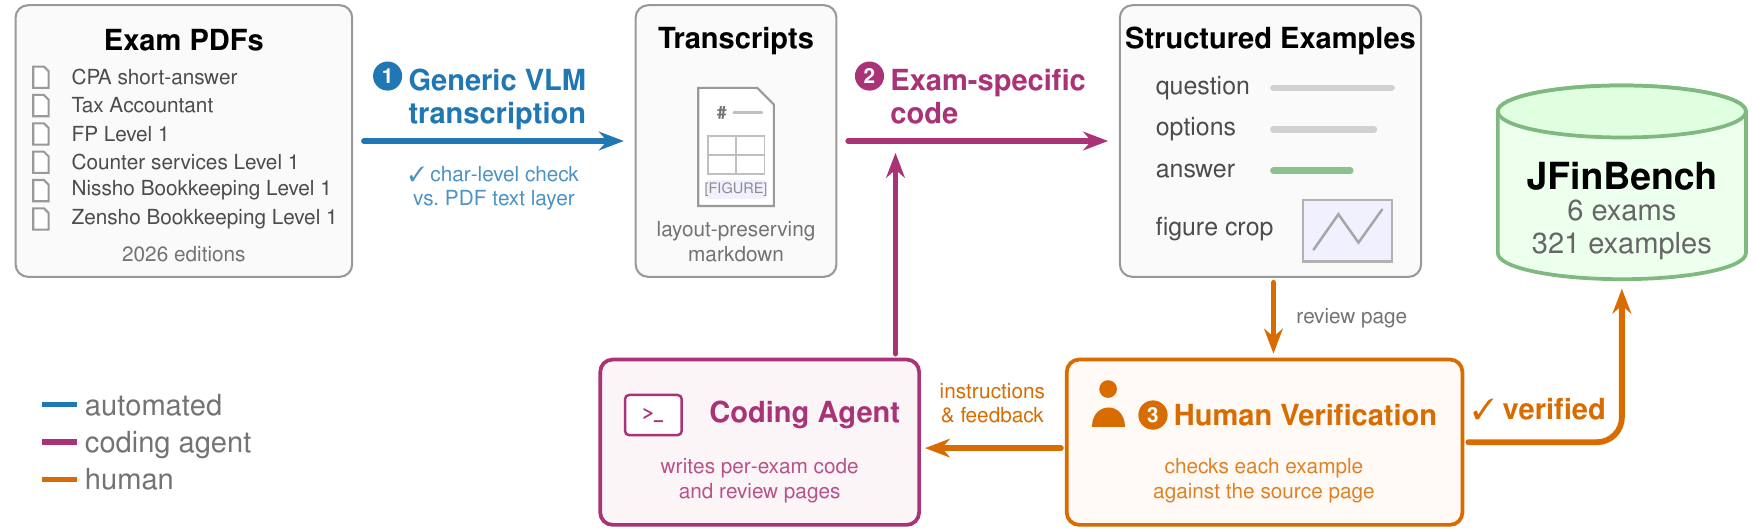
JFinBench is a Japanese financial benchmark comprising 321 examples from the 2026 editions of six certification exams. Constructing a benchmark from publicly available exam PDFs is challenging: the documents have heterogeneous layouts, complex tables and figures, and diverse question and answer formats. We address these challenges with a human-in-the-loop agentic pipeline: a vision-language model transcribes PDFs into layout-preserving Markdown, a coding agent writes exam-specific conversion code and review interfaces, and a human verifies every example and provides feedback for the agent to make corrections. The pipeline requires roughly two hours of human verification per exam, making it practical to refresh the benchmark as new exams are released.
Evaluating 12 LLMs, we find that the leading proprietary models score above 93%, while the best open-weight model trails by 12 percentage points, primarily due to gaps in specialized knowledge. Giving models web and terminal access improves every model's performance and narrows this gap, but about 4 percentage points remain, and the ranking of models changes little (Spearman ρ = 0.87). This suggests that knowledge stored in the model itself remains important even when models can look things up.
264 of the 321 examples are hosted on Hugging Face under the publishers' terms. The rest (the Nissho and Zensho Bookkeeping questions and answers, and the answer keys of the Tax Accountant exam, Nissho, and the FP applied section) is not redistributed: recipes in the repository rebuild it, byte for byte, from the PDFs you download from the publishers, so the full benchmark can be evaluated.
| Exam | Exam date | Question types | Examples |
|---|---|---|---|
| CPA short-answer exam | May 24, 2026 | MCQ | 93 |
| Certified Public Tax Accountant exam | Aug 4–6, 2026 | Answer forms, essays | 40 |
| FP skill test Level 1 (written) | May 24, 2026 | MCQ, short answer | 65 |
| Financial counter services skill test Level 1 | May 2026 (CBT) | MCQ, short answer | 66 |
| Nissho Bookkeeping Level 1 | Jun 14, 2026 | Short answer, answer form | 24 |
| Zensho Bookkeeping Level 1 | Jun 28, 2026 | Short answer | 33 |
Task examples
Citation
@misc{jfinbench2026,
  title         = {JFinBench: A Continuously Refreshable Japanese Financial Benchmark from the Latest Certification Exams},
  author        = {Issa Sugiura and Taro Makino and Takashi Ishida},
  year          = {2026},
  eprint        = {2611.18130},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2611.18130}
}