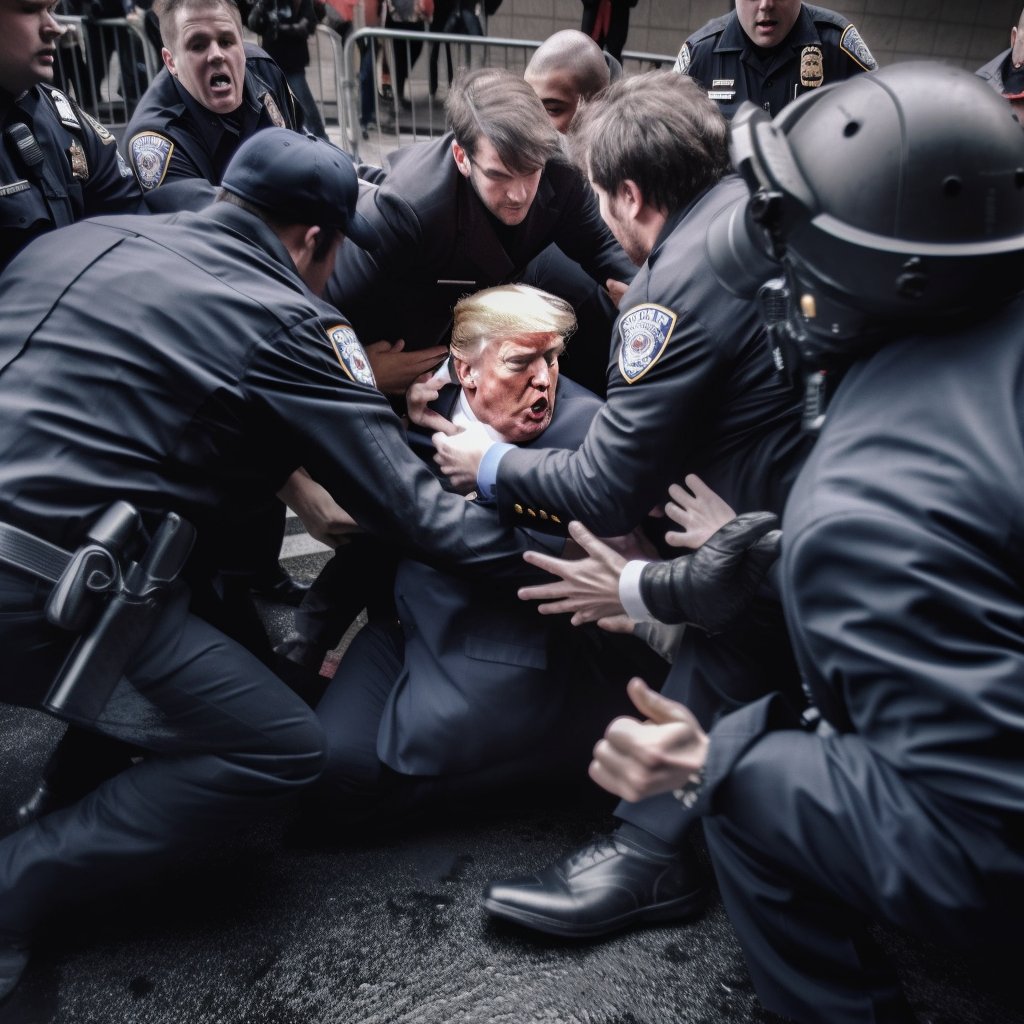
 AI-generated · Midjourney
20 March 2023
Fictional Trump arrest
The source thread disclosed the generation; later copies did not always preserve that context.
Across two complementary studies, we introduce Percept-Lens, an out-of-distribution evaluation framework, and a Mah-NCM-based detector built on frozen visual features. The framework exposes failures in released AI-generated image detectors, while our Mah-NCM-based detector recovers a strong real-versus-generated signal from a general-purpose frozen visual encoder.
The core insight
Why detection matters
On 20 March 2023, Eliot Higgins posted a fictional sequence of Donald Trump's arrest made with Midjourney.1 The original thread identified the images as generated, but as copies travelled beyond it, that context did not always travel with them. AFP traced reshared versions and found comments treating some of them as genuine.2
This was not an isolated incident, as only four days later another Midjourney image of Pope Francis in a white puffer coat went viral and fooled many viewers.3 In May 2023, an AI-generated image of an explosion near the Pentagon spread as breaking news before officials confirmed that no such incident had occurred.4 More recently in January 2025, synthetic images showing the Hollywood sign burning circulated during the Los Angeles wildfires even though the landmark remained intact.5 The cases differ in intent and harm, but share a failure mode that fabricated pixels moved faster than their provenance.
Misinformation cases
AI-generated · Midjourney
20 March 2023
The source thread disclosed the generation; later copies did not always preserve that context.
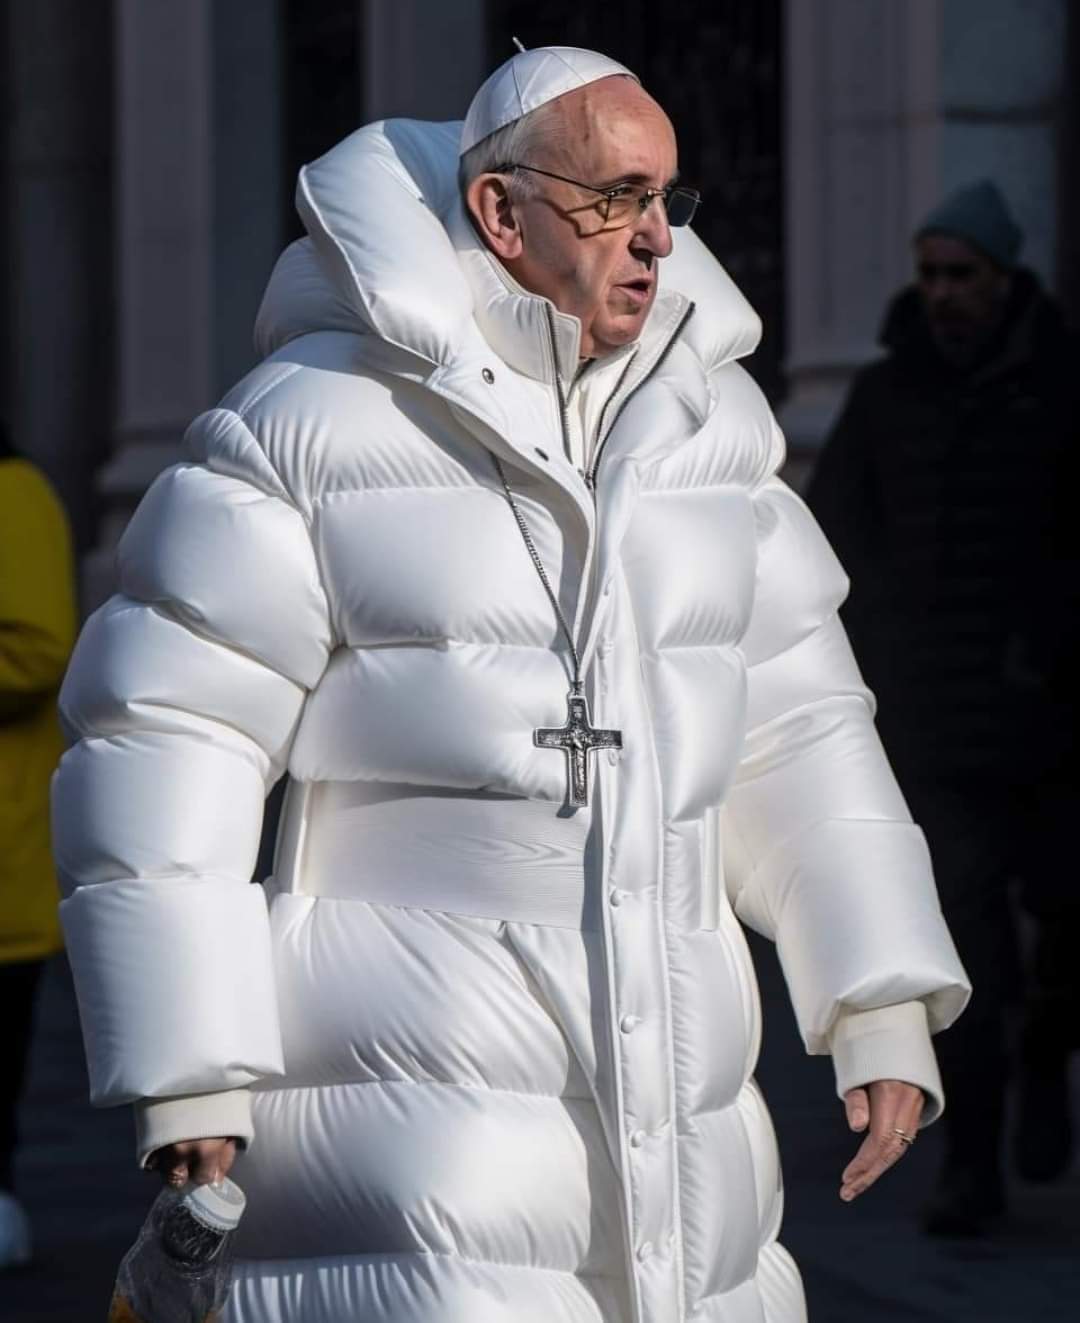 AI-generated · Midjourney
24 March 2023
The photorealistic image spread widely, with many viewers initially taking it as a photograph.
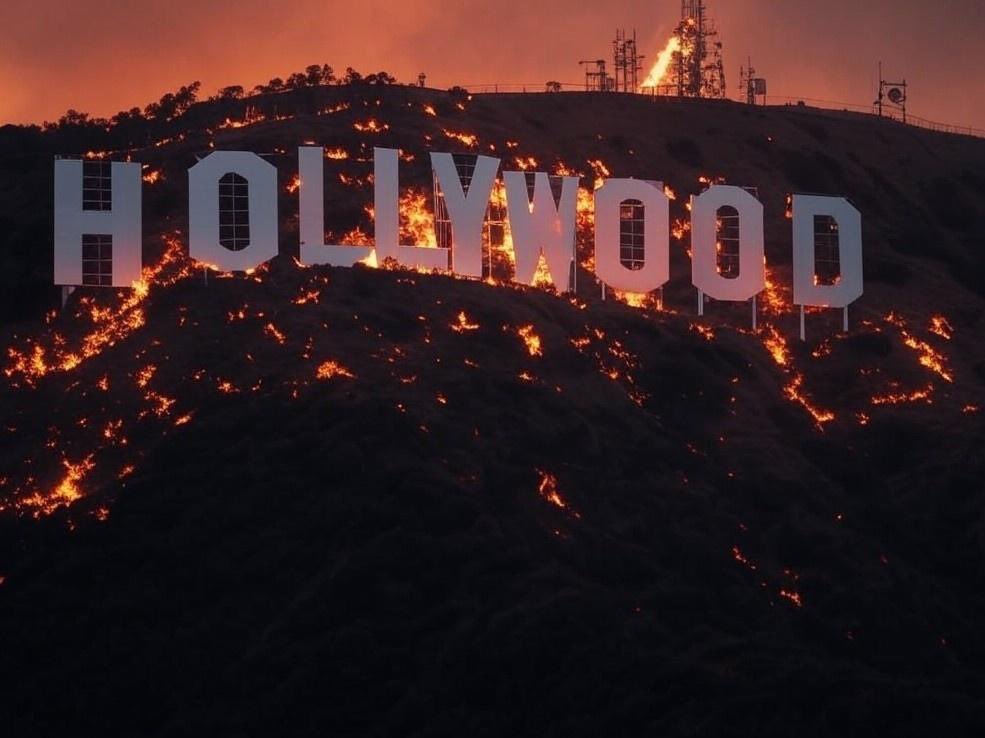 AI-generated · Creator unknown
9 January 2025
The image circulated during real wildfires, but the landmark had not burned.
As images move between platforms, provenance information can be lost. Context still determines where an image came from, what it means, and how it is being used. When that context is missing, a detector can contribute one clue by estimating whether the image appears real or generated.
Many existing detectors perform strongly when their training and evaluation images share familiar generators, prompts, subject matter, and processing.678 Real-world deployment is far less controlled, as a new generator may introduce unfamiliar styles, images may come from a different domain, and a platform may resize or compress them before they reach the detector. The central question is whether the real-versus-generated distinction still holds when these changes arrive together. Here, transfer means remaining effective as generators, prompts, content, and processing change. The benchmark measures how well detectors do so in unfamiliar settings.
This work makes two complementary contributions. First, the Percept-Lens evaluation framework measures how released detectors perform under broad distribution shift. Second, the representation study proposes a new detector that combines a frozen visual encoder with a Mah-NCM decision rule.
Measuring transfer — Benchmark Study
The Percept-Lens evaluation framework brings together more than 36 million images from 26 datasets in a common test of distribution shift. It covers changes in generators, prompts and styles, and image domains, allowing familiar-data performance to be compared with performance under much broader conditions.
To measure how existing detectors perform under this broad shift, we evaluate four released AI-generated image detectors. These include UnivFD9 with a CNNSpot10 training prior and three DRCT7 variants with GenImage8 or Stable Diffusion11 priors. The transfer benchmark below compares each detector's familiar-data result with its broader out-of-distribution result.
Transfer benchmark
Hover, focus, or tap an out-of-distribution point to see its change from the paired in-distribution accuracy.
Swipe horizontally to inspect all four detectors.
Static summary. All four released detectors show lower accuracy outside their familiar distributions, with drops ranging from 19.83 to 35.79 percentage points.
| Detector · Training prior | ID accuracy | OOD accuracy | Accuracy change |
|---|---|---|---|
| UnivFD · CNNSpot | 84.68% | 48.89% | −35.79 pp |
| DRCT · GenImage | 82.36% | 62.53% | −19.83 pp |
| DRCT · SDv1 | 76.85% | 57.00% | −19.85 pp |
| DRCT · SDv2 | 85.92% | 59.85% | −26.07 pp |
The benchmark study also points to a practical way to improve transfer. In controlled comparisons, detectors trained with diverse, open-ended web captions transferred better than those trained with object-centric captions, while simply adding generators yielded smaller gains. Prompt and image variety mattered alongside generator count. These comparisons show how training data shapes transfer, but not which detector components preserve a usable real-versus-generated distinction as distributions shift.
Diagnosing transfer — Representation Study
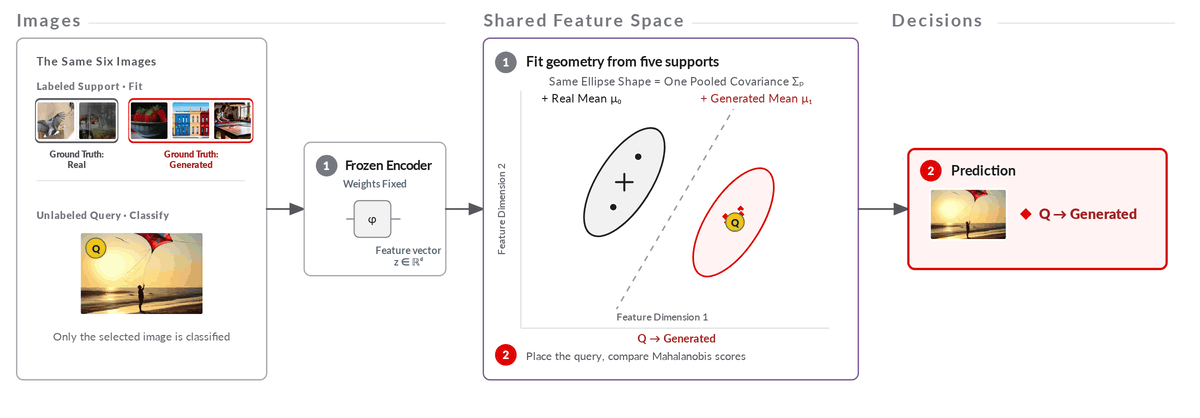
The representation study broadens the Percept-Lens evaluation framework to 39 public datasets and 7.1 million images. An AI-generated image detector has three components. The labeled reference set used to fit it is the support prior. The frozen encoder represents each image while its weights remain fixed, and the classification head turns those features into a decision. We hypothesize that a frozen visual encoder already captures the distinction between real and generated images, so we use a prior-conditioned Gaussian head to recover the decision boundary directly from its features. Rather than updating the encoder or training the head iteratively, our method fits the head from the class means and covariance of the labeled support features. This turns classical Gaussian rules into a closed-form detector that we test under broad out-of-distribution shift.
Our proposed detector first uses a frozen encoder φ to map an image x to a feature vector z = φ(x). It then fits a closed-form Gaussian head from labeled support images. The method illustrated here uses Mahalanobis-Nearest Centroid Matching (Mah-NCM), which estimates the real and generated class means μc and one pooled covariance Σ. The illustration projects this high-dimensional process into two dimensions for visualization. The study uses the full-dimensional feature vectors. In the interactive illustration below, we show how the method classifies an image. Choose and label one image as the query. The other five form the labeled support set used to fit the shared geometry.
Interactive illustration
Choose any one image
Choose any image to begin.
Swipe horizontally to follow the full method.
Decision rule
Here, z is the query feature, μc is the estimated class mean, and Σ† is the stable pseudoinverse of the regularized pooled covariance Σ. With uniform class priors, the query is assigned to the class with the lower squared Mahalanobis score. Unlike Euclidean nearest-centroid matching, this score accounts for feature scale and correlation, so displacement along a broad, noisy direction matters less than the same displacement across a narrow one. Sharing one covariance across classes preserves this geometry while keeping the decision boundary linear.
The Gaussian ladder compares closed-form rules on the same frozen features and labeled support data. Euclidean and cosine nearest-centroid rules use class means. Gaussian naive Bayes (GNB) adds per-dimension variances. Mah-NCM uses one full covariance shared by both classes, while quadratic discriminant analysis (QDA) fits a separate full covariance to each class. The study stabilizes these covariance estimates in high-dimensional feature spaces with diagonal loading and shrinkage.
Compare every ladder assumption in the table below.
| Rule | What it tests | Covariance assumption | Boundary |
|---|---|---|---|
| Euc-/Cos-NCM | Whether class centroids alone separate the features | Shared isotropic | Linear |
| GNB | Whether per-dimension scales suffice without correlations | Class-specific diagonal | Non-linear |
| Mah-NCM | Whether one correlation-aware geometry fits both classes | Shared full | Linear |
| QDA | Whether the classes need different shapes and orientations | Class-specific full | Quadratic |
Mah-NCM is strongest in 9 of 11 matched comparisons, while QDA leads in the two DRCT cases. The result distinguishes settings well described by one shared geometry from those that benefit from class-specific covariance.
To compare our Mah-NCM-based detector with released methods, we replace each released classification head with Mah-NCM while keeping the corresponding public training data and frozen features fixed. We compute mean class accuracy within each evaluation dataset and then average all 39 datasets equally. In this like-for-like comparison, our Mah-NCM decision rule achieved higher mean class accuracy in 10 of 11 cases. The six detector families are UnivFD9, AIDE12, Effort13, DRCT7, CoDE6, and Community Forensics14.
CF-384 was the only exception. Its released decision rule reached 87.54% mean class accuracy, compared with 84.55% for Mah-NCM under the same encoder and support prior. For this fixed representation and evaluation, the original decision rule performed better. Mah-NCM was stronger in the other 10 comparisons, while CF-384 shows that it is not universally optimal.
Matched comparison
Hover or focus a Mah-NCM point to see its difference from the released head.
Headline result. Mah-NCM is higher in 10 of 11 matched comparisons. CF-384 is the one exception.
Swipe horizontally to inspect every matched pair.
Static summary. Mah-NCM has the higher mean class accuracy in 10 of 11 matched rows. CF-384 is the exception, with 87.54% for the released head versus 84.55% for Mah-NCM.
| Released detector | Support prior | Released head | Mah-NCM |
|---|---|---|---|
| UnivFD | CNNSpot | 54.63% | 57.62% |
| AIDE | CNNSpot | 56.41% | 62.76% |
| AIDE · GenImage-SDv1 | GenImage-SDv1 | 48.99% | 57.35% |
| DRCT | Full GenImage | 65.77% | 73.01% |
| AIDE · full GenImage | Full GenImage | 54.98% | 64.64% |
| DRCT | SDv1 | 63.36% | 65.21% |
| DRCT | SDv2 | 62.37% | 67.91% |
| Effort · GenImage-SDv1 | GenImage-SDv1 | 72.58% | 76.82% |
| CoDE-kNN · ELSA | ELSA | 64.01% | 66.15% |
| CF-224 | CommunityForensics | 81.98% | 82.61% |
| CF-384 | CommunityForensics | 87.54% | 84.55% |
Having isolated the classification head, we next examine the two ingredients it depends on. The frozen encoder defines the feature space, while the labeled support prior is used to estimate the class distributions within it. The encoders in this sweep are general-purpose visual encoders that were not trained or fine-tuned specifically for real-versus-generated detection. Community Forensics14 and Mah-NCM stay fixed while only the encoder changes. PE-Core-bigG-14-44815 achieves the highest mean class accuracy among the tested encoders, 94.46%. We therefore use it as the fixed encoder for the complementary support-prior sweep. There, PE-Core and Mah-NCM stay fixed while only the labeled support data changes. The encoder candidates differ in architecture, training objective, data, and resolution. The sweep therefore compares complete encoder models rather than isolating any one design choice.
The model links below identify the exact checkpoints. The encoders come from the CLIP16, MAE17, BEiT18, SigLIP19, BLIP20, BLIP-221, DINOv222, and DINOv323 families.
| Frozen Encoder | Mean CA |
|---|---|
| ResNet-50 | 72.00% |
| ResNet-101 | 70.27% |
| ResNet-50x4 | 72.34% |
| ResNet-50x16 | 74.98% |
| ResNet-50x64 | 74.57% |
| ViT-B/16 | 74.18% |
| ViT-B/32 | 70.61% |
| ViT-L/14 | 76.96% |
| MAE-Huge | 69.37% |
| BEiT-Large | 61.78% |
| CLIP-XLM-RoBERTa-Large | 77.67% |
| SigLIP-Large | 64.14% |
| BLIP-Large | 70.17% |
| BLIP2 | 77.73% |
| DINOv2-giant | 73.30% |
| DINOv3-ViT-7b | 88.91% |
| PE-Core-bigG-14-448 | 94.46% |
| Support Prior | Mean CA |
|---|---|
| CNNSpot | 77.93% |
| GenImage | 92.43% |
| DRCT | 83.25% |
| ELSA | 94.45% |
| Community Forensics | 94.46% |
Our strongest tested detector combines PE-Core, Mah-NCM, and the Community Forensics support prior. The next question is how many labeled images are needed to estimate its class geometry. We use progressively smaller subsets of the Community Forensics prior while keeping the encoder and Mah-NCM fixed. With 219 labeled images (0.005% of the full labeled set), PE-Core + Mah-NCM reaches 90.89% mean class accuracy, compared with 94.46% with the full set.
Support sweep
Headline result. 219 labeled images reach 90.89% mean class accuracy, 3.35 points above CF-384's 87.54% result. The full labeled set reaches 94.46%.
Swipe horizontally to inspect the full accuracy curve.
Static summary. PE-Core + Mah-NCM rises from 85.56% mean class accuracy with 44 labeled images to 90.89% with 219 and reaches 94.46% with the full labeled set. A grey dashed line marks CF-384's 87.54% result.
| Support | Images | Mean CA | Reported min–max |
|---|---|---|---|
| 0.001% | 44 | 85.56% | 83.81–87.40% |
| 0.005% | 219 | 90.89% | 89.55–91.62% |
| 0.01% | 439 | 91.55% | 90.86–92.22% |
| 0.1% | 4,387 | 93.18% | 92.64–93.60% |
| 1% | 43,868 | 93.52% | 93.35–93.80% |
| 100% | 4,386,820 | 94.46% | Not reported |
Transfer in practice
The benchmark recorded the examples below as errors from six released detectors. Our Mah-NCM-based detector classifies the same images correctly, showing where its frozen representation retains a useful real-versus-generated distinction as generators, prompts, styles, and image domains change.
Benchmark examples
Selected shift
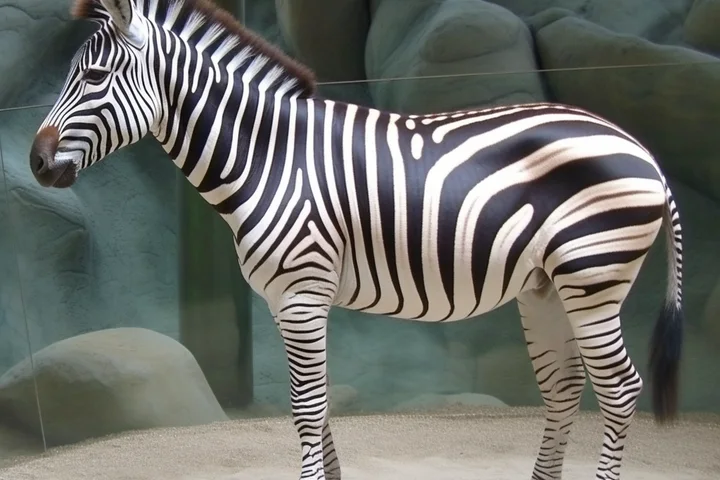
The examples span six generators. Each released detector misses an AI-generated image that our Mah-NCM-based detector classifies correctly.
 ADMOur Mah-NCM Detector → AI-generated
 MidjourneyOur Mah-NCM Detector → AI-generated
 DALL·E 2Our Mah-NCM Detector → AI-generated
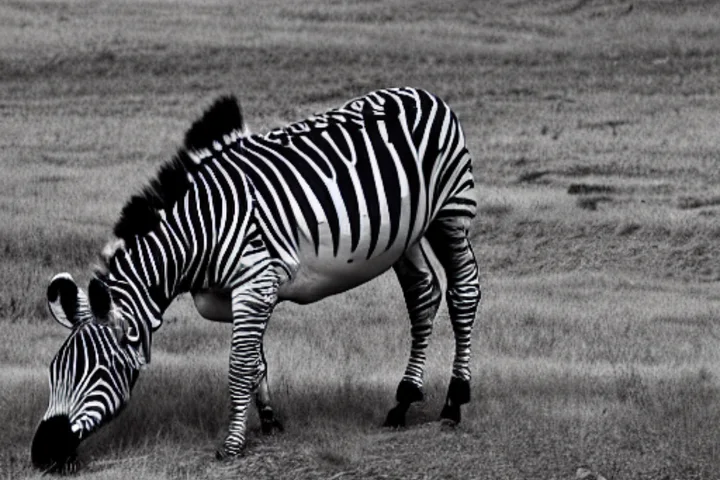 Stable Diffusion 1.4Our Mah-NCM Detector → AI-generated
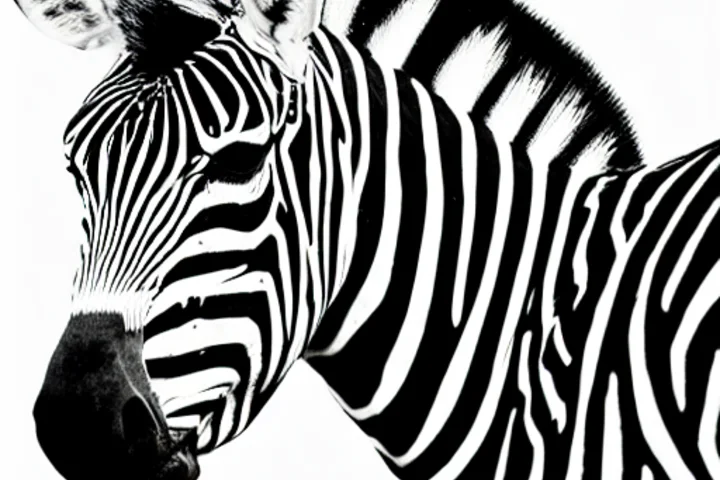 Stable Diffusion 1.5Our Mah-NCM Detector → AI-generated
 WukongOur Mah-NCM Detector → AI-generated
We also applied our Mah-NCM-based detector to newly generated photorealistic images from ChatGPT Images 2.0 and Nano Banana 2. The examples span varied subjects, styles, and image domains. The wider benchmark tests whether detector improvements continue to transfer as generators evolve. If detectors that perform well on it fail on future generators, the benchmark will need to expand.
Current-generator check
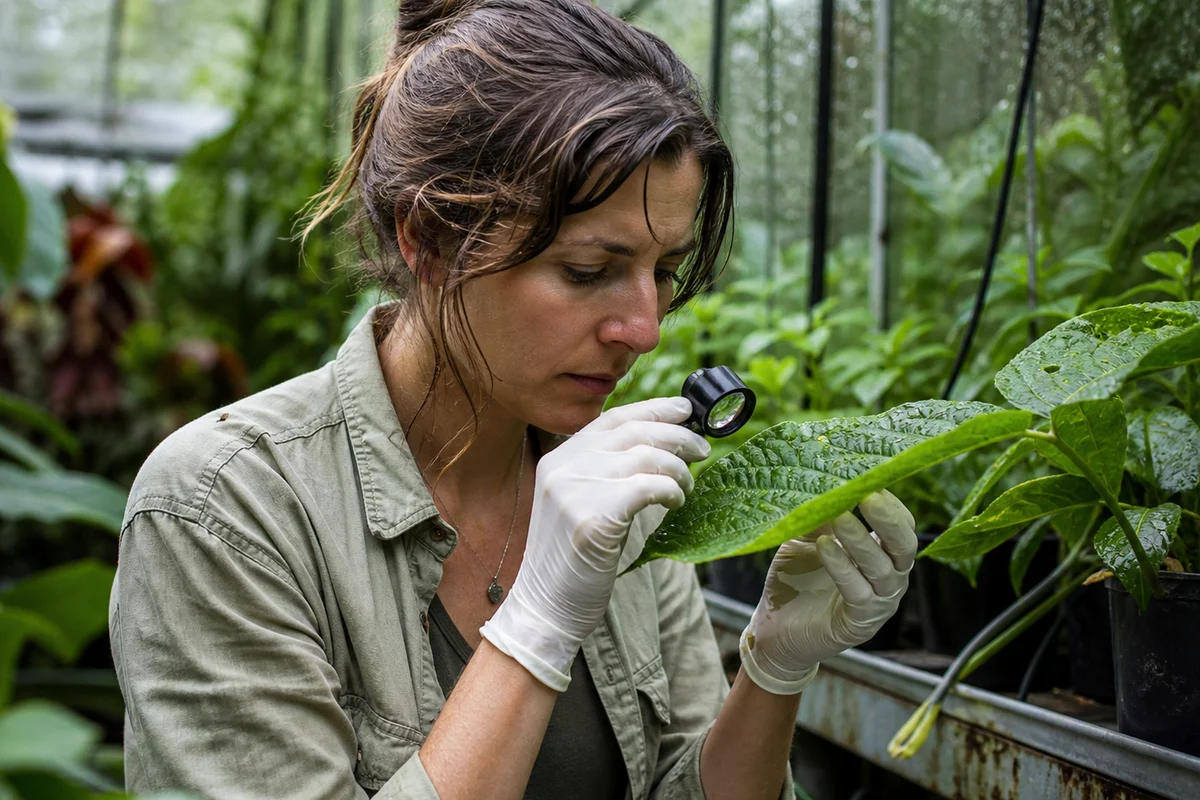 ChatGPT Images 2.0 · People & documentary
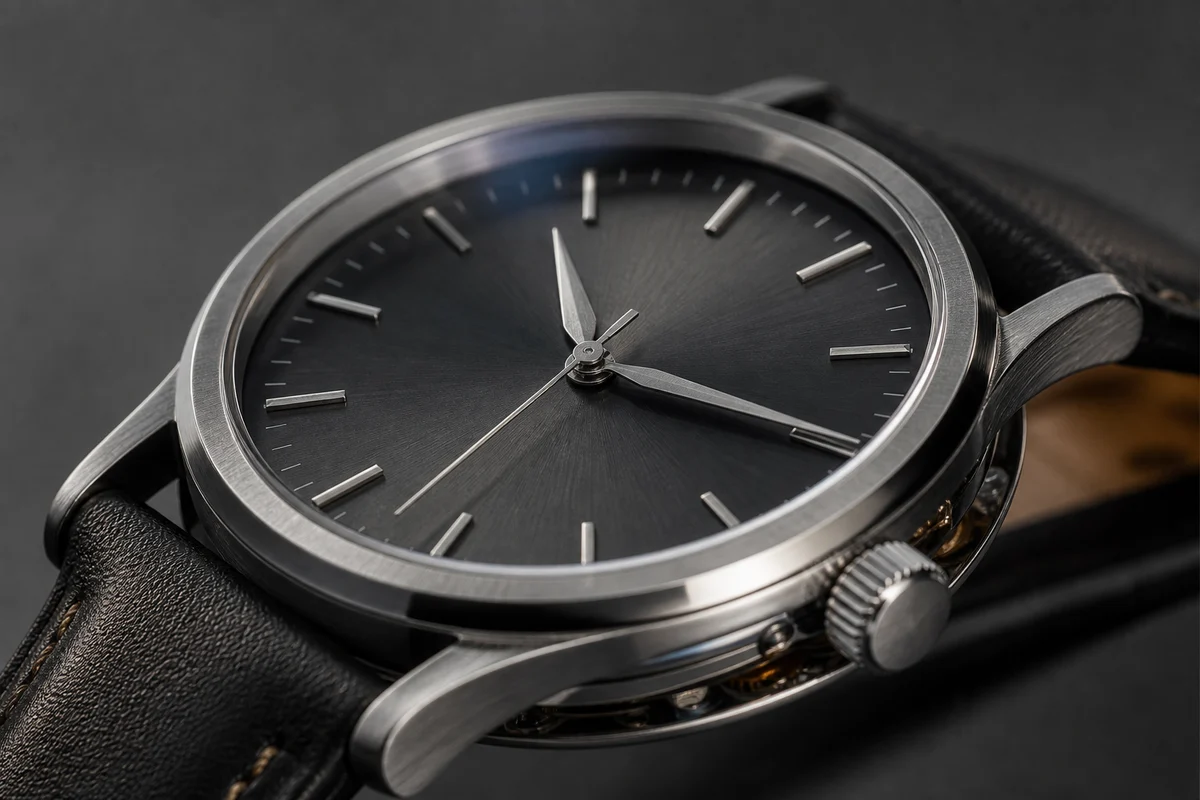 ChatGPT Images 2.0 · Product photography
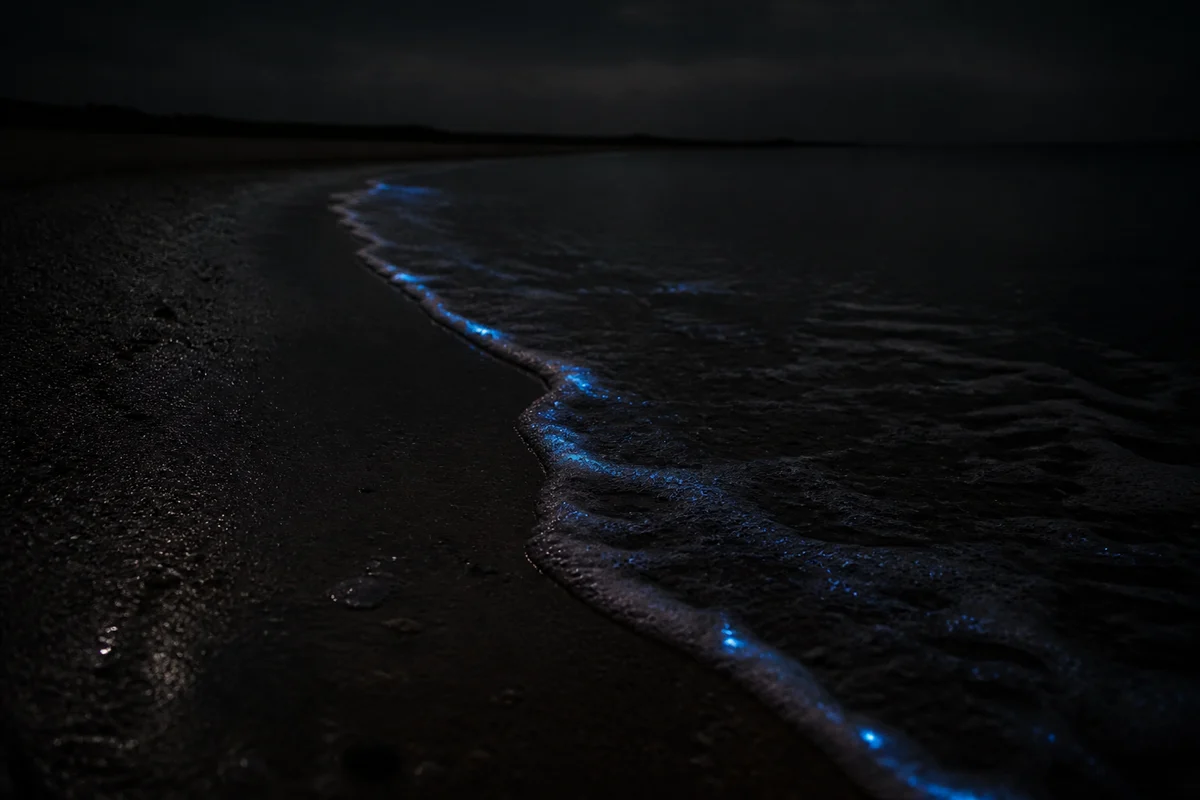 ChatGPT Images 2.0 · Natural phenomena
 Nano Banana 2 · Wildlife photography
 Nano Banana 2 · Architecture & interiors
 Nano Banana 2 · Food & still life
Takeaway
Detection can contribute one signal to media verification alongside context and provenance. The detector estimates whether an image is real or generated, while context and provenance explain where it came from and how it is being used.
Together, the studies move from evaluating transfer to improving it. Percept-Lens reveals where released detectors fail, while the representation study introduces our Mah-NCM-based detector and shows whether the next improvement should target the data, visual encoder, or decision rule. In the tested settings, our strongest detector reached 94.46% mean class accuracy, showing that frozen visual features already separate real and generated images.
@inproceedings{kotyan2025perceptlens,
  title     = {Percept-Lens: A Large-Scale Benchmark for Generalization in AI-Generated Image Detection with Diverse Images and Generative Models},
  author    = {Kotyan, Shashank and Imajuku, Yuki and Shing, Makoto and Clanuwat, Tarin},
  booktitle = {CVPR Workshop on Responsible Generative AI},
  year      = {2025}
}@inproceedings{kotyan2026prior,
title = {Prior-Conditioned Gaussian Discriminants for Generalizable {AI}-generated Image Detection},
author = {Kotyan, Shashank and Shing, Makoto and Imajuku, Yuki and Charakorn, Rujikorn and Clanuwat, Tarin},
booktitle = {European Conference on Computer Vision},
year = {2026}
}This work also supported Sakana AI's participation in the Japan–U.S. Global Innovation Challenge 2025, and feeds into our wider efforts on identifying disinformation.


